Choosing an Agentic AI Framework in 2026: It Depends What You're Actually Building
Ask five developers which agentic AI framework to use in 2026 and you’ll get five different answers, and honestly, all five might be right. The field has moved past the point where one tool tries to be everything to everyone. What’s emerged instead is a set of frameworks that each optimize for a different pressure: some for control, some for speed of prototyping, some for type safety, some for a specific cloud ecosystem. The smarter question isn’t “which framework is best” — it’s “what does my project actually need to get right.”
When the priority is control and auditability
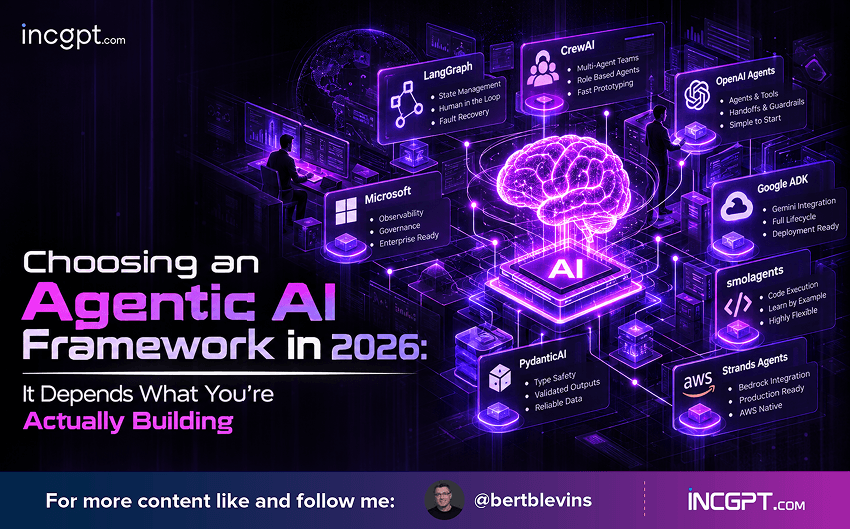
If an agent is going to run in production and touch anything that matters — customer data, financial actions, irreversible steps — the priority shifts from flexibility to control. LangGraph is built for exactly this. It treats an application as a graph of states and transitions, so you can build in branching logic, pause points for human approval, and checkpoints that let a workflow resume cleanly after a failure instead of restarting from zero. It’s not the framework that gets you a flashy demo in twenty minutes. It’s the one that holds up when a support system or coding assistant has to run reliably for months without surprising anyone.
Microsoft’s Agent Framework sits in a similar camp, though it comes from a different angle. It merges what used to be split across AutoGen and Semantic Kernel into one framework spanning Python and .NET, with a heavy emphasis on observability, middleware, and governance. It’s less about chasing developer excitement and more about giving enterprise teams — especially ones already inside the Azure or Microsoft 365 ecosystem — a predictable, auditable way to run agents at scale.
When speed to prototype matters more than architecture
Not every project needs that level of rigor on day one. CrewAI has become popular precisely because its mental model is so easy to grasp: assign agents roles, hand them tasks, and let a “crew” — a researcher, an analyst, a writer, a reviewer — work through a process together. For research tools, internal reporting, and early-stage multi-agent experiments, that’s often enough to get something working fast, even if it eventually needs tighter guardrails around tool access and output-checking before it goes near production.
The OpenAI Agents SDK plays a related role for teams that want a single well-scoped agent rather than a full crew. Built around agents, tools, handoffs, and guardrails, it keeps the API surface small enough that you can start with one focused agent and only add orchestration once there’s a real reason to. It’s a natural fit if your stack already leans on OpenAI’s models, though it offers less structure than LangGraph for workflows that need to persist and recover over long stretches of time.
When your ecosystem is already decided
For a lot of teams, the framework decision isn’t really open — it’s already been made by whichever cloud platform the rest of the company runs on. Google’s Agent Development Kit is the clear pick for teams building on Gemini, Vertex AI, or Cloud Run; it covers the full lifecycle from agents and memory to evaluation and deployment, with a local UI for testing before anything ships. It’s evolving quickly, though, so pinning versions and testing upgrades carefully is worth the discipline.
Strands Agents leans the same way for AWS shops, particularly those already using Amazon Bedrock. Rather than mapping out every step in advance, it lets the model reason about which tools to reach for and how to proceed, scaling from simple assistants to more autonomous workflows. That flexibility is useful for open-ended tasks, but it puts more weight on strong tool boundaries and validation once an agent’s decisions start to carry real consequences.
When reliability of output matters more than autonomy
Some problems don’t need a model that improvises — they need one that returns exactly the right shape of data, every time. PydanticAI exists for that use case. It brings the type safety and validation that made Pydantic and FastAPI popular in the Python world into agent development, so instead of hoping a model returns usable JSON, you get properly typed, validated Python objects. That’s the difference between an agent you can trust to write to a database or generate a financial report and one you have to babysit.
When you want to see the machinery, not just use it
Hugging Face’s smolagents takes an unusual approach worth knowing about even if you don’t end up using it in production: instead of a large JSON schema for every action, it lets models write short Python code to call tools directly. The core loop is small enough to actually read end to end, which makes it a genuinely good way to learn how an agent works rather than just consume it as a black box. That same code-execution flexibility is also its biggest risk — running model-generated code demands real sandboxing and tightly scoped permissions, not an afterthought bolted on later.
When the app is a web product, not just a backend script
Mastra fills a gap that a lot of the Python-first frameworks leave open: full-stack TypeScript teams building agent-driven products with React, Next.js, or Node.js. Its clean separation between agents (for when the model needs room to decide) and workflows (for predictable, pre-defined steps) makes it practical for production web apps that need both AI flexibility and dependable application logic living in the same codebase.
When the hard part is the data, not the decision-making
LlamaIndex built its reputation on retrieval, and its Workflows framework extends that strength into agentic territory. It uses an event-driven structure — each step reacts to an event, does its work, and emits the next one — which naturally supports branching, parallel execution, and multi-stage research pipelines. It’s the right tool when the real challenge isn’t which tool an agent should call next, but finding, extracting, and properly grounding answers in the right documents. For enterprise search, document analysis, and RAG-heavy systems, that’s usually the harder problem to solve well.
The actual decision
None of these frameworks are competing to be crowned the best one. They’re solving different problems, and the right choice comes down to being honest about which problem you actually have: Do you need airtight control over every step, or a fast prototype? Do outputs need to be strictly validated, or is some model improvisation fine? Is your team already locked into a cloud ecosystem, or building something cloud-agnostic? Answer those questions first, and the framework choice tends to answer itself.